

Web Application Integration
Two systems disagreeing about the same customer is not an integration problem. It is an ownership problem that integration made visible.
- Typical duration
- Two to eight months
- Team shape
- Two to four senior engineers
- Starts with
- A record ownership review
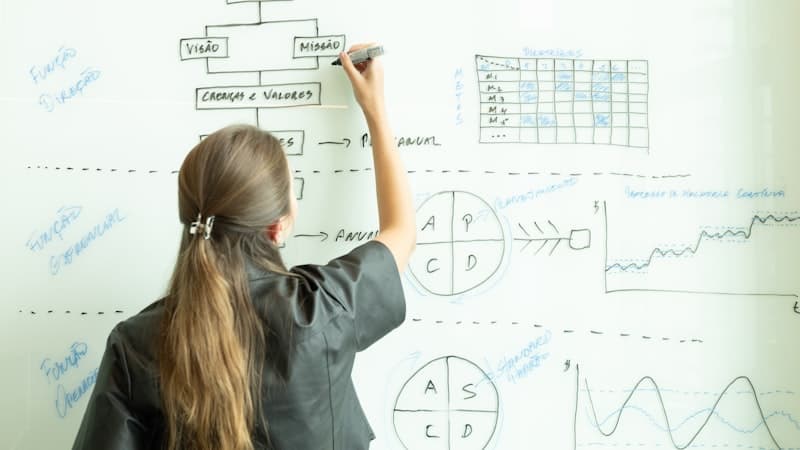
Decide who owns the record before deciding how to move it
Almost every integration that goes wrong went wrong at the same point: two systems ended up believing they were authoritative for the same field, and the sync started resolving that disagreement by whichever wrote last.
So the first piece of work is not technical. It is agreeing, per record and sometimes per field, which system is the source of truth and which are readers — and getting the people who own each system to agree to it in writing. Once that exists, the engineering is well-understood: idempotent writes, explicit retries, a dead-letter path, and enough observability that a partner outage is visible before a customer reports it.
What usually goes wrong, and what we do instead
The pattern is consistent enough that we now start every integration the same way.
Where integrations go wrong
- Two systems both treated as authoritative for the same field
- A nightly job that copies data and quietly diverges between runs
- Retries that duplicate records because the write is not idempotent
- Failures swallowed by a job that reports success anyway
- A partner API change discovered by a customer rather than an alert
How we build it instead
- One owner per record, agreed in writing with the system's owner
- Events rather than copies, so readers derive rather than duplicate
- Idempotent writes with explicit retry and backoff semantics
- A dead-letter path that is monitored and has an owner
- Contract tests against each partner, run on a schedule
What we build
The parts of an integration that decide whether it wakes people up.
Record ownership design
Which system is authoritative for what, agreed in writing with the teams that own them.
API and partner integration
REST, GraphQL, SOAP and the file drops that older systems still insist on.
Event-driven sync
Changes published once and consumed by many, so readers derive their view rather than keeping a copy.
Idempotency and retries
Repeated deliveries handled as no-ops, with backoff and a dead-letter path that has an owner.
Contract testing
Tests against each partner's interface, run on a schedule, so a breaking change is caught by us.
Per-partner observability
Dashboards and alerts by integration, so an upstream outage is attributable in seconds.
How the pieces fit together
The same shape whether there are two systems or twenty: one owner per record, an integration layer that translates, and readers that derive rather than copy.
What each part does
- The system of record: the one place a given record can be changed, agreed with its owner before anything is built.
- The integration layer: translation and validation in one place, so a partner's field names never leak into your domain.
- The event stream: changes published once and consumed by many, so readers derive their view rather than holding a copy.
- Idempotency and retry: every write carries a key, so a repeated delivery is a no-op rather than a duplicate record.
- The dead-letter path: what cannot be processed goes somewhere visible with an owner, rather than into a log nobody reads.
- Observability: per-partner dashboards and alerts, so an outage upstream is seen here before a customer reports it.
How the work runs
The same five stages as every engagement, applied to systems that have to agree.
Diagnose
What flows where today, what each system believes it owns, and where those beliefs conflict.
Decide
Record ownership, the sync mechanism and the failure semantics, written down and agreed with each system's owner.
Prove
One integration end to end in production, including its failure case, its retry and its dead-letter path.
Deliver
Integrations built one at a time, each monitored and stable before the next is scoped.
Hand over
Your team runs it with us watching, then without us.
What we build it with
Chosen for what an integration has to survive when the other side is having a bad day.
Interfaces
- REST
- GraphQL
- Kafka
- Temporal

Services
- Node.js
- TypeScript
- Java
- Spring Boot
- Python
Data
- PostgreSQL
- Redis
- MongoDB
- Elasticsearch

Platform
- AWS
- Azure
- Kubernetes
- Datadog
- Sentry


What you get, and when
Handed over as it is produced, not assembled at the end.
- A map of what flows where today, measured rather than described
- Record ownership agreed in writing, per system
- The failure semantics for each integration, decided up front
- Source in repositories you own
- Contract tests per partner, running on a schedule
- A monitored dead-letter path with a named owner
- Per-partner dashboards and alerts
- A runbook for each alert, including what not to retry
- A written record of every agreed ownership decision
The rest of our web work
Most web engagements touch two or three of these. If you are not sure which, the consultation is the way in.
Related work
Engagements where several systems had to agree about the same thing.
Questions about integration
The ones we are asked most often before a first conversation.
Should we just buy an integration platform?
What if two teams both think they own the record?
One of the systems is ancient and has no API.
Does this have to be real time?
What happens when the other system goes down?
How do we find out when a partner changes their API?
Systems that disagree with each other?
Tell us which systems and which records. We will tell you where the ownership conflict is.